Write-ups of my research and side projects, meant to be read rather than cited: the intuition behind a paper, with the visualizations the paper had no room for, next to experiments and notes that never became one. Expect diffusion language models, optimization curiosities, and the occasional self-hosting or finance side-project.
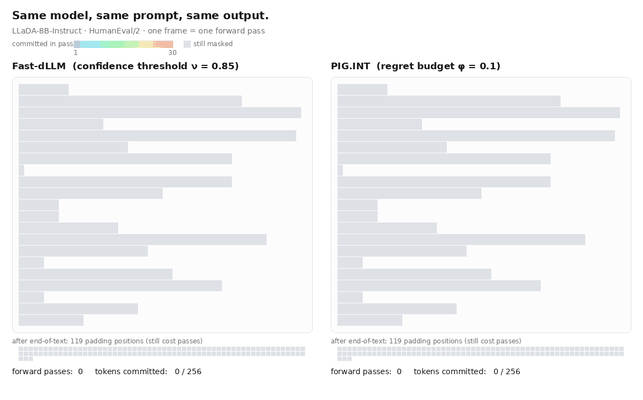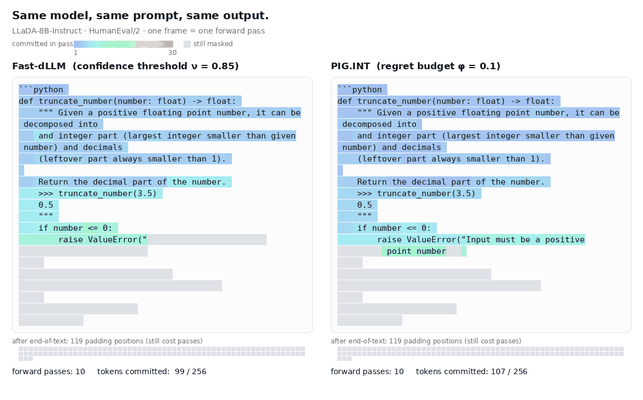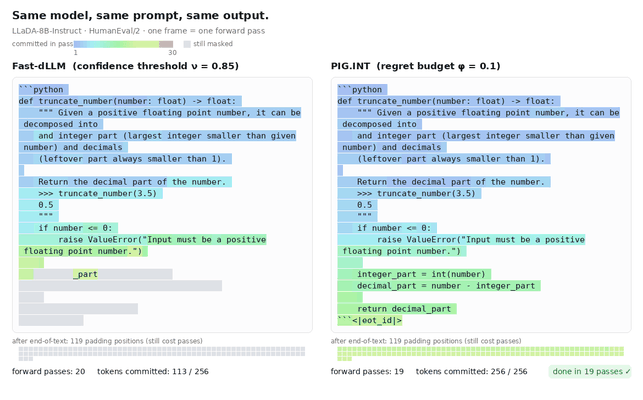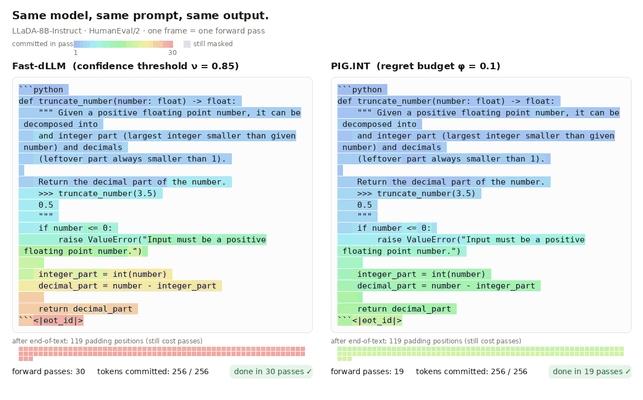
Parallel decoding is fast until tokens that cannot see each other disagree. PIG predicts, from the forward pass the model already makes, which tokens would come out differently if decoded one at a time, and commits only the ones that would not. A 2M-parameter adapter, under 0.1% of a forward pass, trained once per model: same outputs, fewer passes.
Read the post →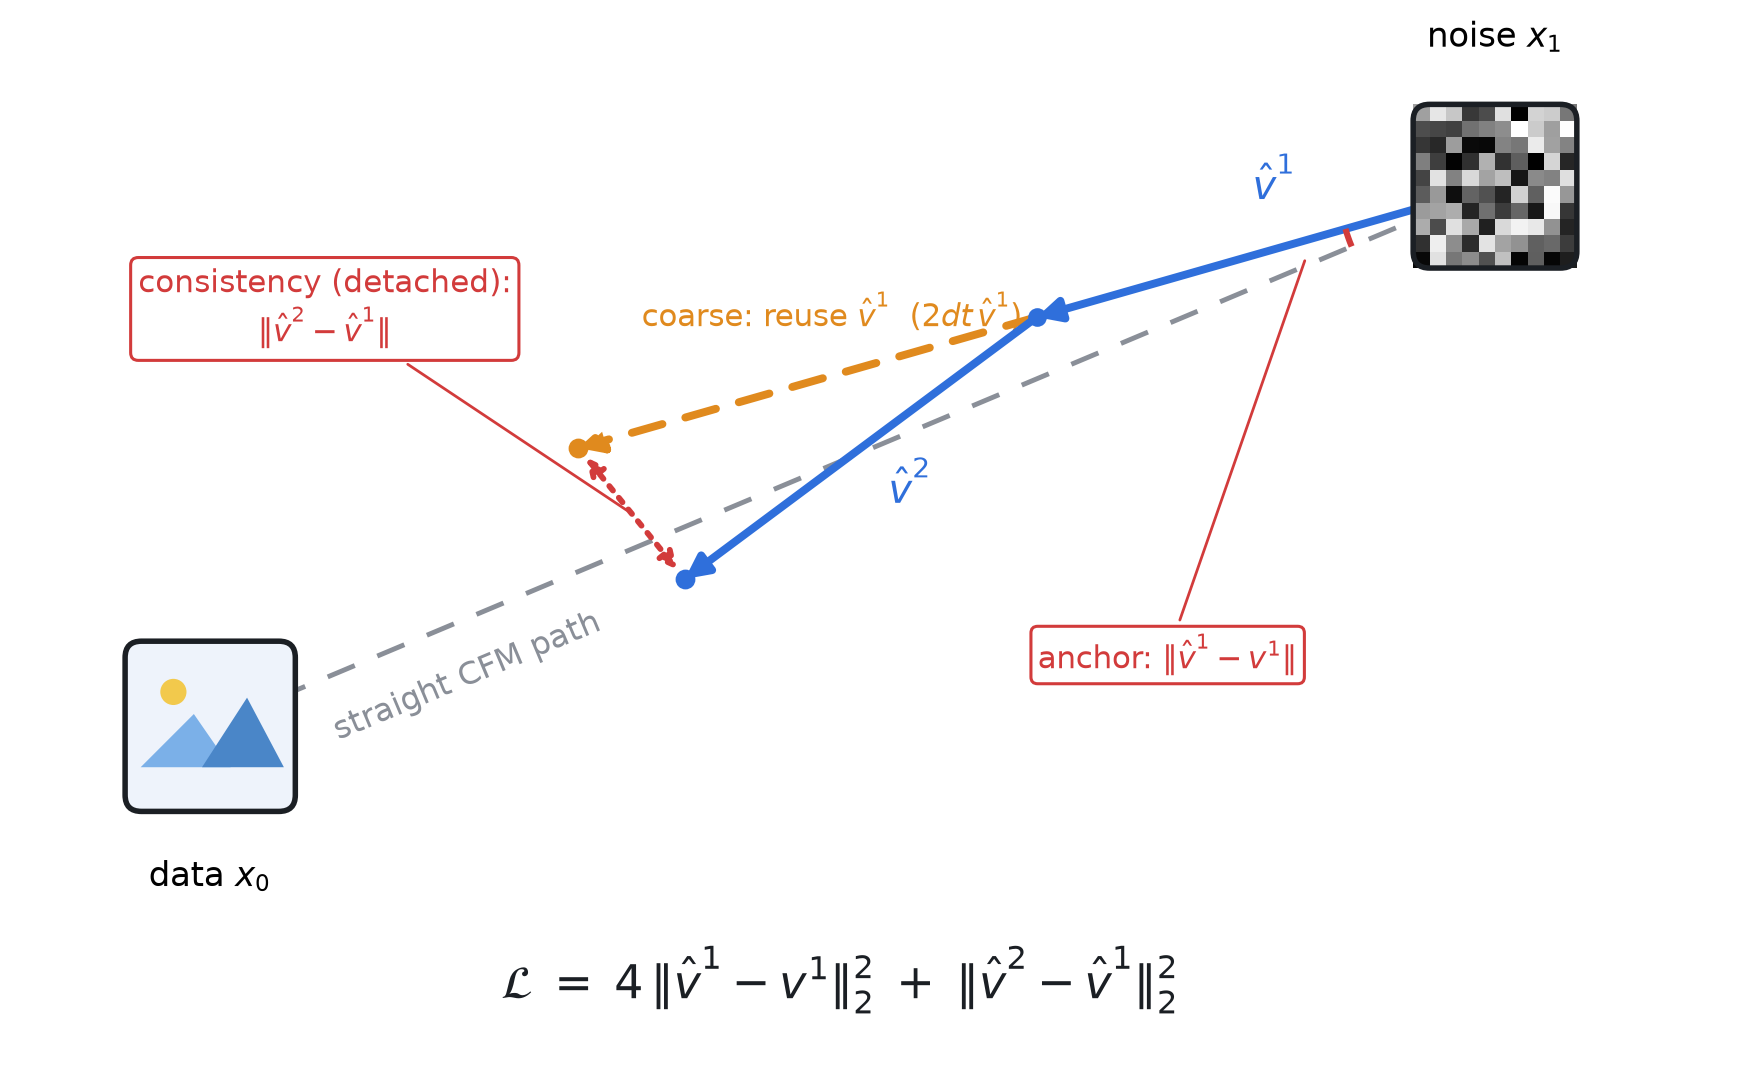
Training flow-matching models the way they're actually sampled (unrolling + BPTT) turns out to quietly reduce to consistency and shortcut models — once you apply a gradient-variance argument. Full manuscript PDF linked.
Read the post →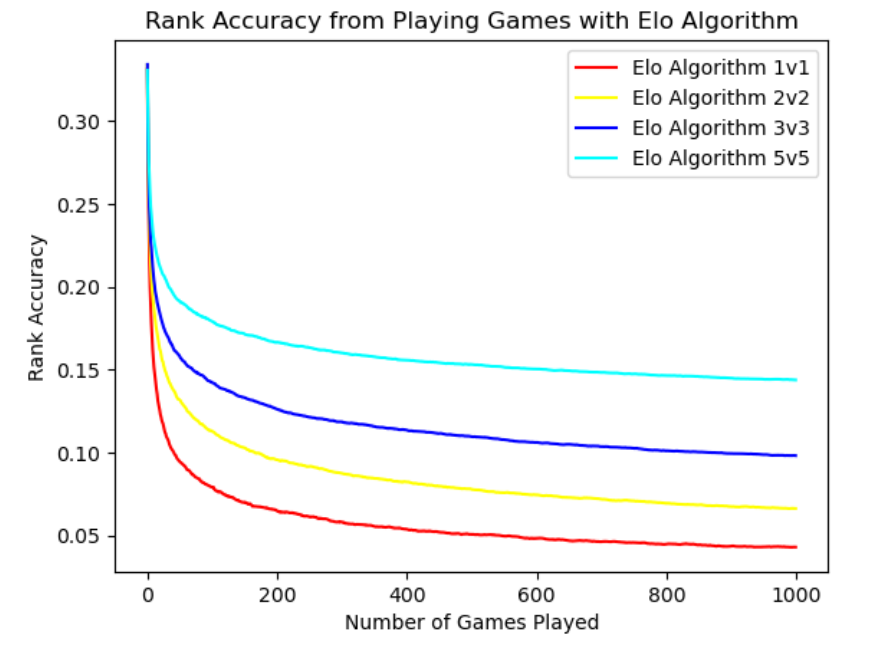
A course project: why Elo, Glicko, and Glicko-2 degrade sharply as team size grows in n-vs-n esports — a simulation study, and the case for performance-aware ratings.
Read the post →